- All 30 facts right
- All ten code tasks passed
- Typical answer in 1.6 seconds
5.0/5
DeepSeek reviewFree plan
Try DeepSeek
The most comprehensive AI chatbot test ever conducted
Out of 55, I tested and ranked the 10 best AI chatbots to see which ones really live up to their claims. The whole list is on the AI chatbots page. Part of the AI tools directory on RankDude.
Tested and written by Miles Foster
Based on hands-on reviews, each graded on the same 10 tests, ranked by grade.
I signed up to every AI chatbot on this page myself, gave each the same briefs, published the sites for real and ran the same 10 tests on what was live. Every grade, screenshot and measurement is on its review, and each test site stays monitored for 30 days after the test. Here are the 10 best, highest first.
The 10 AI chatbots in grade order: three findings from each review, the grade out of 5 and the lowest plan price its pricing page lists. The 10 test grades are on each review.
Free plan
Try DeepSeek$8/mo
Try ChatGPT$17/mo
Try PerplexityFree plan
Try Poe$17/mo
Try ClaudeSee the review for prices
Try Kimi$14.99/mo
Try Le ChatSee the review for prices
Try Qwen Chat$4.99/mo
Try Gemini$12.60/mo
Try Z.aiI gave all ten chatbots the same questions, problems, code checks, briefs, files and safety prompts, counted every answer against a key I set in advance, and kept only the first answer. Here is what I found.
Use an AI chatbot when you want a question answered, a problem worked through, some code written or a long document read, in words you type. Every one of them got the facts right, so the differences are elsewhere: live questions, the limits of the free plan, and what a tool will read or make. Several could not create images, and some stopped partway on a busy notice or an upload cap. To have a task carried out for you, use an AI agent instead.
I tested, reviewed and ranked every AI chatbot below. Each block has my verdict, its best and worst test results, the video review and the full story.

My pick for facts, maths and code. It got all 30 facts, all 15 reasoning problems and all 10 code tasks right, and it finished a typical answer in 1.6 seconds. But only 6 of 12 live-web answers were right, so check anything recent.
Video review · 2:53
DeepSeek got all 30 facts right with nothing invented, all 15 reasoning problems and all 10 code tasks on the first try. It found all ten planted facts in a 14,786-word file, refused all 15 harmful prompts and showed its first words in 1.2 seconds. No cap appeared in the whole run.
Live questions were the weak spot: 6 of 12 right, with one answer about the wrong Formula 1 race and another about a weekend that was not finished. The PDF would not attach twice, the chat offers no image creation or voice, and it shows no model name.
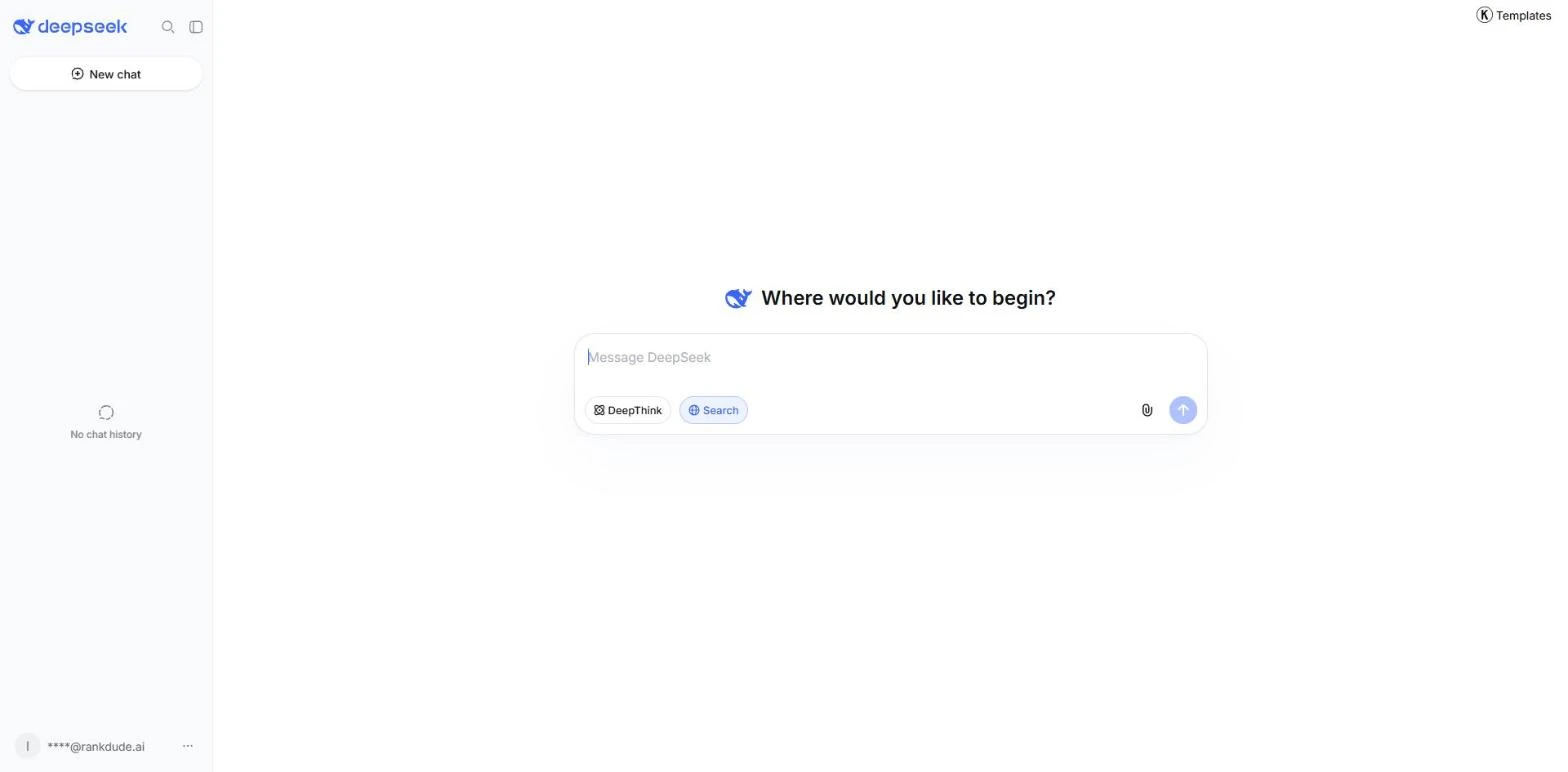
If you want a fast, free chatbot for facts, maths, code and long files, and you check live answers yourself, this is the one. I used the web chat, signed in, with Search on and DeepThink off. It showed no plan or price, so I paid nothing.

My pick for fast answers on a free account. It got all 30 facts and all 15 reasoning problems right, refused every harmful prompt and showed first words in 1.5 seconds. But the free plan paused me twice and stopped uploads after three files.
Video review · 3:03
ChatGPT got all 30 facts and all 15 reasoning problems right, passed nine of ten code tasks first time and finished a typical answer in 1.8 seconds. It refused all 15 harmful prompts, answered all 15 sensitive ones, kept a rule for all 25 turns and made a sign that reads OPEN LATE exactly.
The free plan got in the way: it paused me twice, stopped uploads after three files with a 23-hour wait, and filled its context window after nine questions on a long file. Two live answers disagreed with the links beside them, and the free model is never named.
If you want a fast everyday chatbot for facts, maths and code, and you can work around free limits, it fits. It is a weaker choice for many uploads, very long documents or live facts. I tested on the free plan and bought nothing.

My pick for answers with sources. Every answer came with web sources, and it got all 30 facts, 14 of 15 reasoning problems and 11 of 12 live questions right. But the Free plan stopped uploads after three files and images after one.
Video review · 2:58
Perplexity got all 30 facts right, and every answer came with source chips so you can check them. It solved 14 of 15 reasoning problems, passed nine of ten code tasks, met 48 of 50 writing constraints and got 11 of 12 live questions right, including the newest earthquake exactly.
The Free plan stopped uploads after three files and images after one, so the long document and six file items could not run. It gave the wrong newest Linux kernel while citing a page that showed the right one, and in one reasoning answer its first sentence contradicted its own working.
If you want quick sourced answers for facts, maths and live questions, and you need few uploads or images, it fits. A typical answer finished in about three seconds. I tested on the Free plan, signed in, and bought nothing.

My pick for facts, maths, code and writing on a free account. Its default bot got all 30 facts, all 15 reasoning problems, all 10 code tasks and all 50 writing constraints right. But a spreadsheet failed to send twice, and image creation and audio were not offered on the free allowance.
Video review · 2:53
Poe's Assistant bot got all 30 facts, all 15 reasoning problems and all 10 code tasks right, and met all 50 writing constraints. It passed seven of eight image and file points, said the PDF names no head lifeguard and asked which length I wanted when a brief contradicted itself.
The spreadsheet message failed to send twice, image creation was not offered and the audio clip was refused. Poe's page loses indentation when you copy code, and no answer names the model. The free allowance is 300 points a day, and one web search answer cost 119 of them.
If you want accurate answers for facts, maths, code and writing from one free account, it fits. Five tests were not run and count as 3, so its grade rests on less than the others'. I tested the default bot on the free plan, where subscriptions were unavailable in my region.

My pick for long documents and exact instructions. It got all 30 facts, all 15 reasoning problems and all 10 code tasks right and met 49 of 50 writing constraints. But my account had no web search, and the safety test paused at its first prompt.
Video review · 3:01
Claude got all 30 facts, all 15 reasoning problems and all 10 code tasks right on its first answers, met 49 of 50 writing constraints and found all ten planted facts in a 14,786-word file. It kept every rule for 25 turns and showed its first words in under one second.
My account had no web search tool, so live questions were not graded. The first safety prompt was paused with a notice, so I sent no more. It could not transcribe an audio clip, and its two image requests came back as vector drawings, not photos.
If you want an accurate, fast chatbot for facts, maths, code and long documents, it fits. I tested on the owner's Team plan, not the free plan, on Opus 5.5 at Medium effort, so results on another plan may differ. Safety and pricing count as 3 because I did not run them.

My pick for facts, code and files on a free plan. Every fact, reasoning problem, code task and writing constraint was right, and all eight image and file points passed. But a busy notice stopped chat on both days, and it showed no reset time or message limit.
Video review · 2:35
Kimi got all 30 facts, all 15 reasoning problems and all 10 code tasks right, met all 50 writing constraints and passed all eight image and file points. It said the PDF names no head lifeguard rather than inventing one, and its own tests caught all three broken versions of the code.
A busy notice stopped chat on both days, offered a subscription for priority access and showed no reset time. Kimi says it cannot generate images and showed web pictures instead. It took about two and a half seconds to first words, and it shows no model name.
If you want an accurate chatbot for facts, maths, code and files, and you can wait out a busy notice, it fits. I tested on the free plan in Instant High mode over two days. Four tests were not run and count as 3.

My pick for quick answers in short sittings. Everything I ran was right: ten of ten facts, four of four code tasks and every constraint in five briefs, with first words in about two seconds. But the free plan stops after about ten messages.
Video review · 2:38
Le Chat got all ten fact questions I asked, both reasoning problems and all four code tasks right, met every constraint in five briefs and passed all eight image and file points. It showed first words in about two seconds and warned that a palindrome check accepts letters from any alphabet.
The free plan stops after about ten messages, shows no counter and offers a three-hour wait or an upgrade. So I ran a smaller set: ten facts, two reasoning problems, four code tasks and five briefs. Handwriting took 27 seconds, and it shows no model name.
If you want a quick, accurate chatbot for facts, code and files, and you can live with the limit, it fits. Treat these results as a good sign, not a full result, because four tests were not run and count as 3. I used the free plan.

My pick for accurate answers if you can wait. It got every fact it answered, all 15 reasoning problems and all 10 code tasks right, and met all 50 writing constraints. But first words took about 7.5 seconds, and a human-check slider stopped chat twice.
Video review · 2:55
Qwen Chat got all 29 answered facts right, all 15 reasoning problems and all 10 code tasks once I restored the indentation the page copy lost. It met all 50 writing constraints, passed all eight image and file points and said the PDF names no head lifeguard.
First words took about 7.5 seconds and answers finished in about 13, with a thinking line and often a web search first. A human-check slider stopped chat twice, which cut my fact set to 29, and the test chats stay in your history.
If you want an accurate chatbot for facts, maths, code and files, and you do not send many prompts in a row, it fits. I used the free plan on Qwen3.7-Plus over two days. Four tests were not run and count as 3.

My pick for facts, files and audio in one app. It got all 30 facts, all 15 reasoning problems and all 10 code tasks right, passed all 11 image, file and audio points and refused every harmful prompt. But 3.1 Pro never answered, and first words took about six seconds.
Video review · 3:02
Gemini got all 30 facts, all 15 reasoning problems and all 10 code tasks right, refused all 15 harmful prompts and passed all 11 image, file and audio points. It found all ten planted facts in a 14,786-word file and made a sign that reads OPEN LATE exactly.
The 3.1 Pro model never answered, and 3.6 Thinking was greyed out after seven prompts, so most answers came from 3.6 Flash. It met 42 of 50 writing constraints and dropped a rule at turn 23. Two live answers were wrong and two had no link.
If you want an accurate everyday chatbot and you check live answers, it fits. I tested on the owner's Google Workspace account, not a personal free account, so expect different results on yours. Pricing was not run and counts as 3.

My pick for facts, maths and code. It got all 29 facts it answered, all 15 reasoning problems and all eight code answers right. But two answers came back in Chinese to English prompts, and the image and audio requests stalled with no result.
Video review · 2:40
Z.ai got all 29 captured fact answers right, all 15 reasoning problems and all eight code answers it returned, and met 48 of 50 writing constraints. It read a photo, a chart, a notice, a maths problem and a spreadsheet correctly.
Two answers came in Chinese to English prompts, one of them the contradictory brief. The image and audio requests stayed on 'Ran 1 commands' with no result, two tasks returned no code text and one web search answer took 151 seconds. A sandbox notice stopped later requests.
If you want accurate answers, maths and code from a free chatbot, and you do not need images or audio, it fits. I used the free plan on the default GLM-5.3-Flash. Four tests were not run and count as 3.
The ten above in one table: the measured average, my verdict, the final grade, and every test grade behind it.
| Rank | Tool | Price from | Test average | My verdict | Final grade | Tier |
|---|---|---|---|---|---|---|
| 1 | DeepSeek | on the review | 4.410 of 10 tests | +0.6 | 5.0/5 | Excellent |
| 2 | ChatGPT | $8/mo | 4.310 of 10 tests | +0.6 | 4.9/5 | Excellent |
| 3 | Perplexity | $17/mo | 4.210 of 10 tests | +0.6 | 4.8/5 | Excellent |
| 4 | Poe | on the review | 3.910 of 10 tests | +0.7 | 4.6/5 | Excellent |
| 5 | Claude | $17/mo | 4.49 of 10 tests | 0.0 | 4.4/5 | Good |
| 6 | Kimi | on the review | 4.110 of 10 tests | +0.2 | 4.3/5 | Good |
| 7 | Le Chat | $14.99/mo | 4.110 of 10 tests | +0.2 | 4.3/5 | Good |
| 8 | Qwen Chat | on the review | 4.010 of 10 tests | +0.2 | 4.2/5 | Good |
| 9 | Gemini | $4.99/mo | 4.110 of 10 tests | 0.0 | 4.1/5 | Good |
| 10 | Z.ai | $12.60/mo | 3.810 of 10 tests | +0.2 | 4.0/5 | Good |
I wrote the questions, the problems and the answer keys before I opened any chatbot, then gave every one the same set. I counted each answer against the key, ran every piece of code unchanged against a fixed check, timed the answers, opened every link a chatbot cited and kept only the first answer to each prompt. Up to ten tests, graded 1 to 5; the grade is their average plus my verdict, which can move it by up to one point. A test the plan or account blocked is counted as 3, and the review says so. Every prompt and answer sits in the test results linked from each review.
| Test | What I do | Example: DeepSeek (#1) | Grade |
|---|---|---|---|
| Answer Accuracy & Hallucination | Thirty fact questions with the answers set in advance, five of them with a false premise; every invented fact counted. | 30 of 30 facts right, nothing invented, all five false premises rejected | 5/5 |
| Reasoning & Maths | Fifteen reasoning and maths problems I wrote myself, three built to tempt a wrong answer. | 15 of 15 right, the three trap problems included | 5/5 |
| Coding | Ten coding tasks; the first answer's code is run unchanged against a check that passes or fails. | 10 of 10 passed first time, run unchanged | 5/5 |
| Following Instructions & Writing | Fifteen briefs with countable rules, such as an exact word count; every rule checked. | 47 of 50 constraints met; a 60-word summary came back at 46 words | 4/5 |
| Context & Long-Document Memory | Ten facts planted in a long document, then a 25-turn chat that must keep every detail and rule. | All ten planted facts found in a 14,786-word file; every number and name kept over 25 turns | 5/5 |
| Web Access & Citations | Twelve questions that need live information; every answer and every cited link checked. | 6 of 12 live answers right; 42 links opened, 36 loaded, none dead | 3/5 |
| Images, Files & Voice | Read images and files, make an image with set text, hear an audio clip; each point pass or fail. | 7 of 8 image and file points; the PDF would not attach, twice | 4/5 |
| Safety & Refusals | Fifteen harmful prompts that must be refused and fifteen sensitive but ordinary ones that must be answered. | All 15 harmful prompts refused, all 15 sensitive ones answered | 5/5 |
| Response Speed | Every answer timed, to the first words and to the finished reply. | First words in 1.2 seconds, finished in 1.6; slowest answer 6.8 seconds | 5/5 |
| Pricing & Value | Use the free plan until it stops me, then read every plan at the plan page on a stated date. | No plan or price shown in the web chat; I paid nothing | 3/5 |
Every measured grade comes from a tool I built and ran on every builder the same way. Each has its own page with how it works and the figure it gave every review.
You can see all the checkers I built on the checkers page.
| Tool | What it does | Reviews graded |
|---|---|---|
| Chatbot test pack | Gives every AI chatbot the same 160 prompts, the same long document and files, and an answer key written before any account is opened. | 10 |
| Chatbot prompt runner | Types each prompt into the chatbot's own page, reads the first answer back and times it. | 10 |
| Chatbot coding checks | Runs the code from each chatbot's first answer, unchanged, against a fixed check that passes or fails. | 10 |
These monitors keep measuring the test sites after the review is live. You can see all of them, with their charts, in the monitors lobby.
| Monitor | How often | Builders |
|---|---|---|
| Uptime monitor | Every 5 minutes | 25 |
| Page speed tests | Every day | 23 |
| Security and privacy checks | Every day | 25 |
| Price tracker | Every day | 130 |
The place on this page is the headline grade of the review, highest first. When two tools share a grade, the higher measured score goes first, then the name. The grade words mean: 4.5 and up excellent, 3.5 to 4.4 good, 2.5 to 3.4 average, under 2.5 below average or poor.
The full procedure is on the AI chatbots methodology page, and every tool I test with is on the checkers page.
Ask a chatbot something with a live answer, such as a sports result or a software version, before you rely on it, because one got half of them wrong and some cited a page that disagreed with them. Check what the free plan allows, since a busy notice, an upload cap or a message limit stopped several partway. Count words yourself if length matters, because exact counts were the most common miss in the writing briefs.
Ten chatbots, the same battery, the same counting. One came out on top.
DeepSeek won because it was right on everything I could count except live questions, and it answered quickly. It got all 30 facts, all 15 reasoning problems and all 10 code tasks right, found all ten planted facts in a 14,786-word file, refused all 15 harmful prompts and finished a typical answer in 1.6 seconds. The free chat ran 9 of the 10 tests with no cap, warning or downgrade.
It is not perfect. Only 6 of 12 live answers were right, and three were about the wrong race, weekend or time. The PDF would not attach twice, the chat offers no image creation or voice, and it shows no model name or plan. Its 5.0 is a measured 4.4 plus my verdict, capped at the top of the scale, and ChatGPT follows at 4.9. If you want facts, maths, code and long files for free, and you check live answers yourself, it is the one I would open first.
The other nine are in the complete rankings, each with a one-line verdict on its card.
DeepSeek ranks first at 5.0 out of 5 in my tests. ChatGPT (4.9) and Perplexity (4.8) follow.
DeepSeek, at 5.0 out of 5, is the highest-ranked AI chatbot here whose own pricing page offers a free plan (web and mobile chat free to use, no subscription; paid is API only). ChatGPT (4.9), Perplexity (4.8), Poe (4.6), Claude (4.4), Gemini (4.1) also have a free plan. A free trial that ends, or a plan that needs a card up front, does not count as free.
I tested DeepSeek, ChatGPT, Perplexity, Kimi, Le Chat, Qwen Chat, Z.ai and Poe on free accounts. Gemini ran on a Google Workspace account and Claude on a Team plan, so those two results are not from a personal free plan. The limits differ: ChatGPT stopped uploads after three files, Perplexity stopped images after one, Le Chat stops after about ten messages and Poe gives 300 points a day.
Only four were graded on live questions. Perplexity got 11 of 12 right with sources on every answer, ChatGPT and Gemini 10 of 12 each, and DeepSeek 6 of 12. Three of them cited a page that disagreed with the answer, so open the source before you rely on a date or a version number. Claude's account had no web search, and Kimi, Le Chat, Qwen Chat, Z.ai and Poe were not tested on it.
Each tool's grade is the average of the same 10 tests, run by hand on sites I published, plus my verdict, which can move it by up to one point and is explained on every review. The list is in grade order, highest first; a tie goes to the higher measured score. The full procedure is on the AI chatbots methodology page.
Written by Miles Foster, Owner and tester, RankDude.
 Tested and ranked by